

Lakehouse Plumber
ETL at scale, the way it should be.
Managing dozens of Lakeflow pipelines means writing — and rewriting — thousands of lines of near-identical PySpark. The patterns repeat; only the table names change. Lakehouse Plumber turns concise YAML actions into fully-featured Lakeflow Spark Declarative Pipelines. You describe what each pipeline is — a source to read, a table to write; LHP writes the how as plain, readable Python you own and open in the Databricks editor. Declare your ETL, don’t hand-write it.
See it
The same ingest, three ways: the YAML you write, the Lakeflow code Lakehouse Plumber generates from it, and the two commands that turn one into the other.
Eighteen lines describe a load and a write. The ${...} tokens
resolve per environment, so the same flowgroup runs unchanged in dev and
prod.
# Your first pipeline: ingest CSV files from a volume into a bronze table.
pipeline: bronze_ingest
flowgroup: orders_ingest

actions:
  # 1. Load: stream CSV files from the landing volume with Auto Loader.
  - name: load_orders_csv
    type: load
    source:
      type: cloudfiles
      path: "${landing_path}/orders/*.csv"
      format: csv
    target: v_orders_raw

  # 2. Write: append the streamed rows into a bronze streaming table.
  - name: write_orders_bronze
    type: write
    source: v_orders_raw
    write_target:
      type: streaming_table
      catalog: "${catalog}"
      schema: "${bronze_schema}"
      table: orders
Ordinary Lakeflow Python — a temporary view for the source, a streaming table for the target, an append flow wiring them together. Nothing hidden behind a runtime; you could have written it by hand, but you didn’t.
# Generated by LakehousePlumber
# Pipeline: bronze_ingest
# FlowGroup: orders_ingest

from pyspark import pipelines as dp

# Pipeline Configuration
PIPELINE_ID = "bronze_ingest"
FLOWGROUP_ID = "orders_ingest"


# ============================================================================
# SOURCE VIEWS
# ============================================================================


@dp.temporary_view()
def v_orders_raw():
    """Load data from csv files at /Volumes/dev_catalog/landing/files/orders/*.csv"""
    df = (
        spark.readStream.format("cloudFiles")
        .option("cloudFiles.format", "csv")
        .load("/Volumes/dev_catalog/landing/files/orders/*.csv")
    )

    return df


# ============================================================================
# TARGET TABLES
# ============================================================================

# Create the streaming table
dp.create_streaming_table(
    name="dev_catalog.bronze.orders", comment="Streaming table: orders"
)


# Define append flow(s)
@dp.append_flow(
    target="dev_catalog.bronze.orders",
    name="f_orders_bronze",
    comment="Append flow to dev_catalog.bronze.orders",
)
def f_orders_bronze():
    """Append flow to dev_catalog.bronze.orders"""
    # Streaming flow
    df = spark.readStream.table("v_orders_raw")

    return df
Validate resolves every token and checks the actions; generate writes the Python.
$ lhp validate --env dev
✓ discover (0.01s)
✓ bronze_ingest  0 files
✓ validate (0.38s)
1 validated · 0.4s

$ lhp generate --env dev
✓ discover (0.01s)
✓ bronze_ingest  1 file
✓ generate (0.41s)
1 pipeline generated · 1 file · 0.5s
The payoff compounds. Adding a data-quality check, a second table, or a CDC merge is a few more lines of YAML — not another fifty lines of Python each time. The Get Started course walks through a complete sample project. Then Build your own pipeline helps you author your own.
The model
A common data-flow shape combines one or more loads, zero or more transforms, and one or more writes. Actions connect through the views they read and produce.
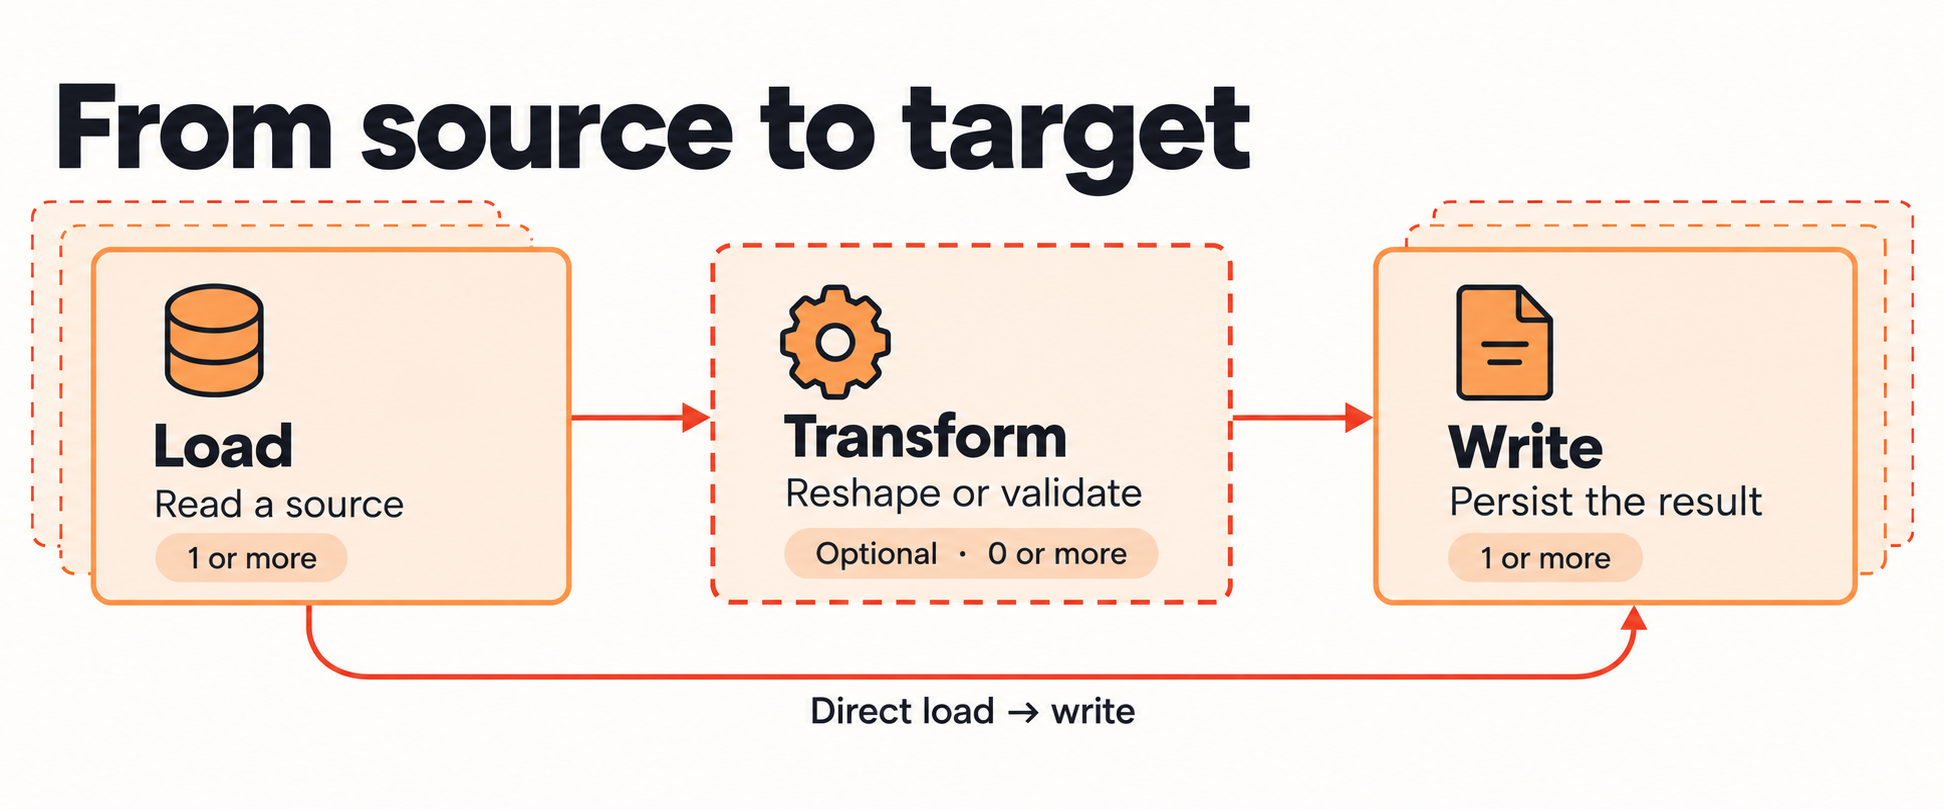
Dotted cards represent additional loads and writes. Transforms are optional, so a load can feed a write directly. Select the diagram to view it full size.
What LHP handles for you
Start with a source and a target, then enable the capabilities your project needs. Monitoring and quarantine extend the same declarative approach to operating pipelines and recovering rejected rows.
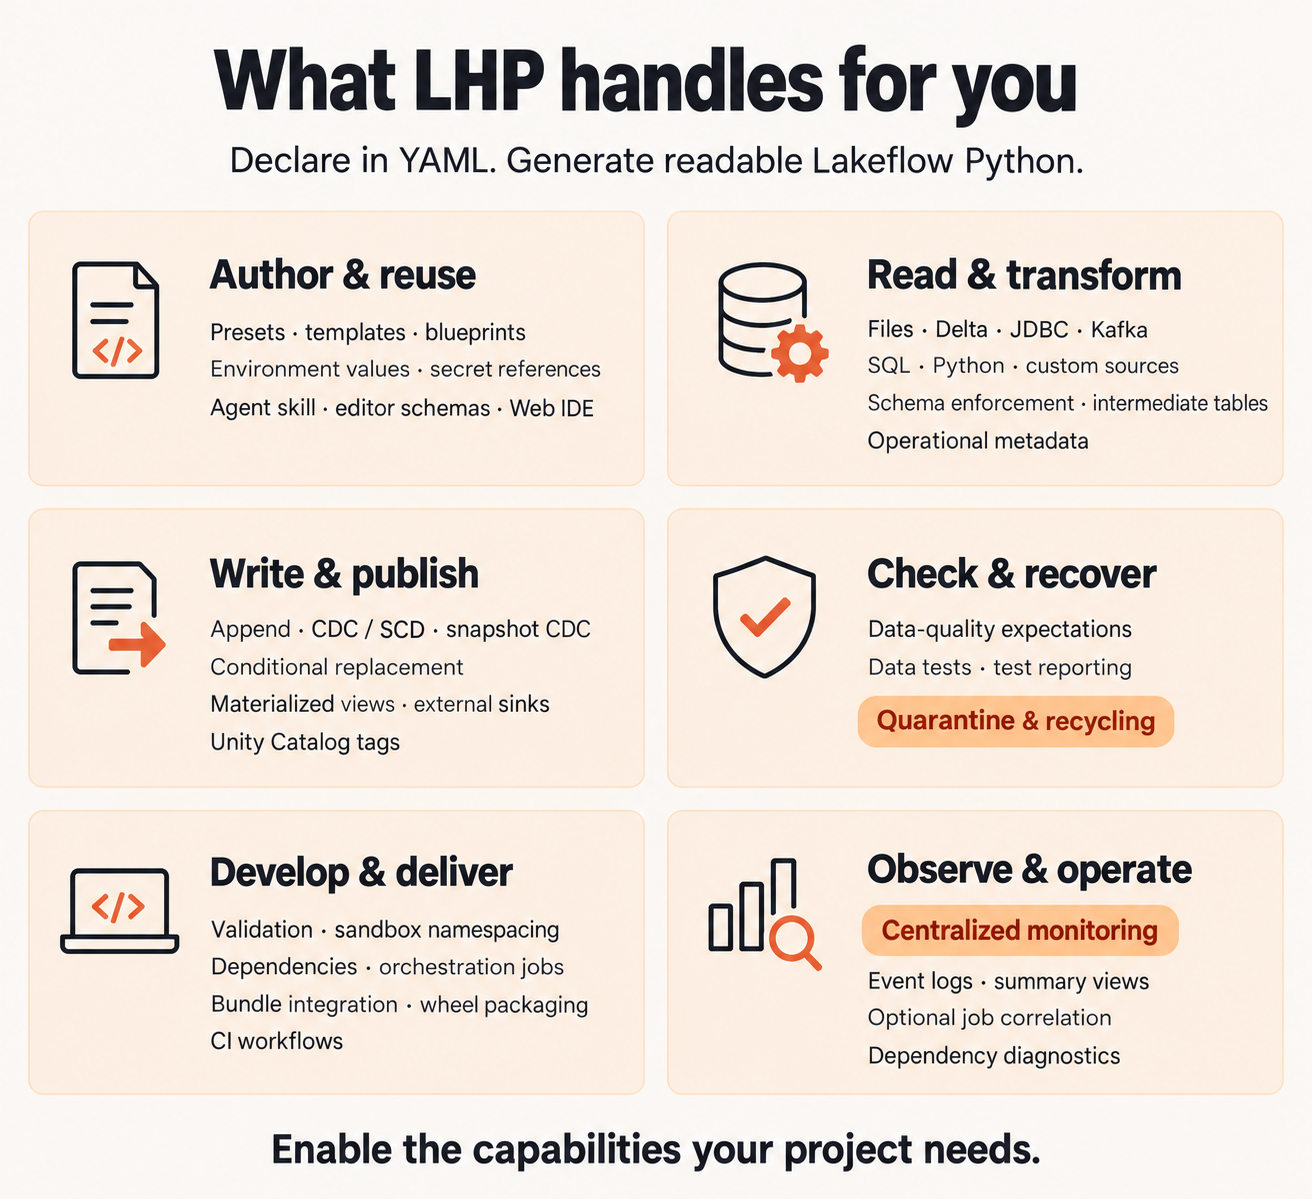
LHP generates the code and configuration for the capabilities you enable. Select the diagram to view it full size.
Author and reuse: Compose flowgroups, environment values and secrets.
Read and transform: sources, transformations, Add table metadata.
Write and publish: streaming tables, views and sinks.
Check and recover: data quality, quarantine and recycling.
Develop and deliver: Develop and deploy.
Observe and operate: centralized monitoring, dependency diagnostics.
Where to next
Run the existing sample course from installation through deployment.
Build with your own data: configure, read, transform, write and check quality.
Develop locally, configure bundles, schedule jobs and deploy through CI.
Enable monitoring, adjust its settings and diagnose problems by symptom.
Find exact action syntax and configuration options by feature or filename.
Coming from DLT?
Already have Delta Live Tables pipelines? See Migrate a DLT pipeline to Lakehouse Plumber.